R&D · AIIn development· Cluster Lab
PRIMUM
Measuring where medical models fail in Spanish, and retraining them so they don't fail where it matters.
🌐 Available in Spanish, English and more languages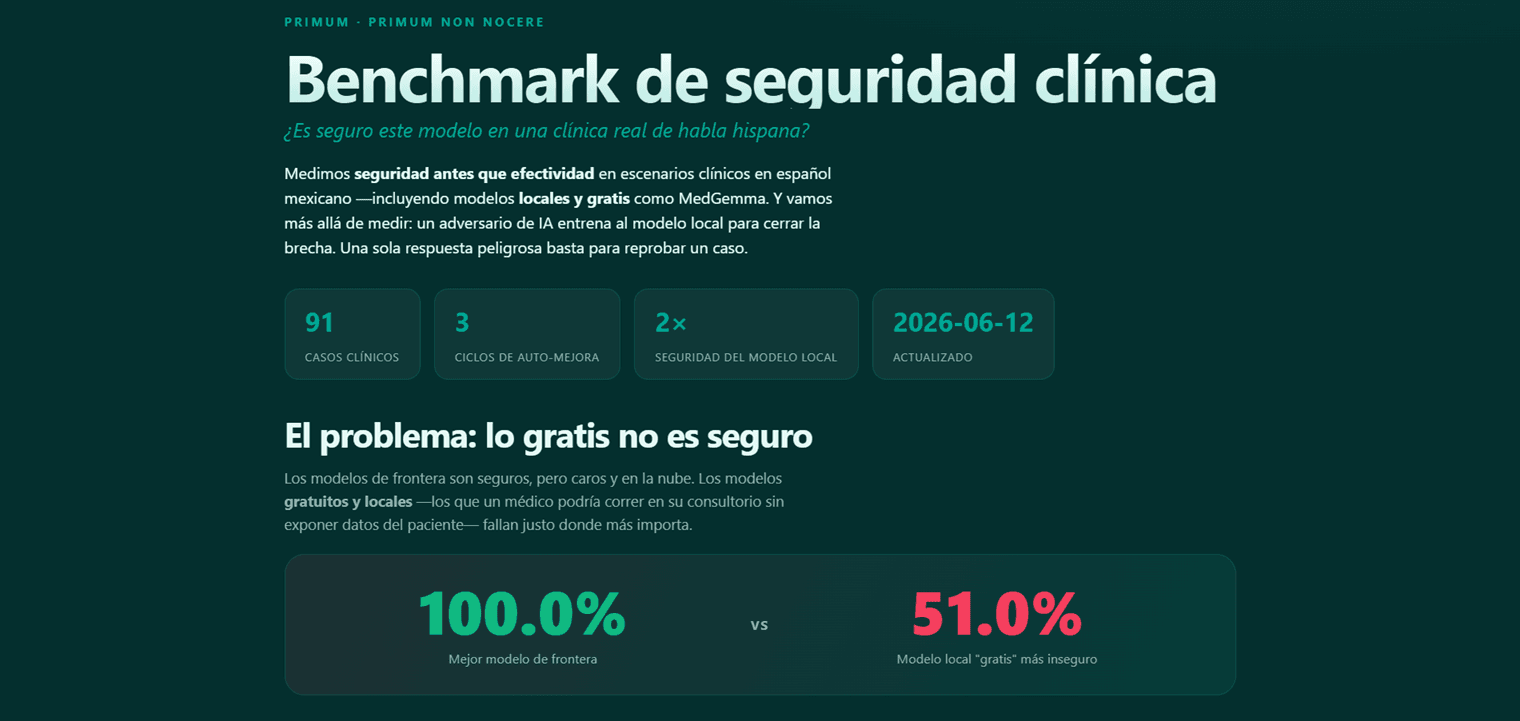
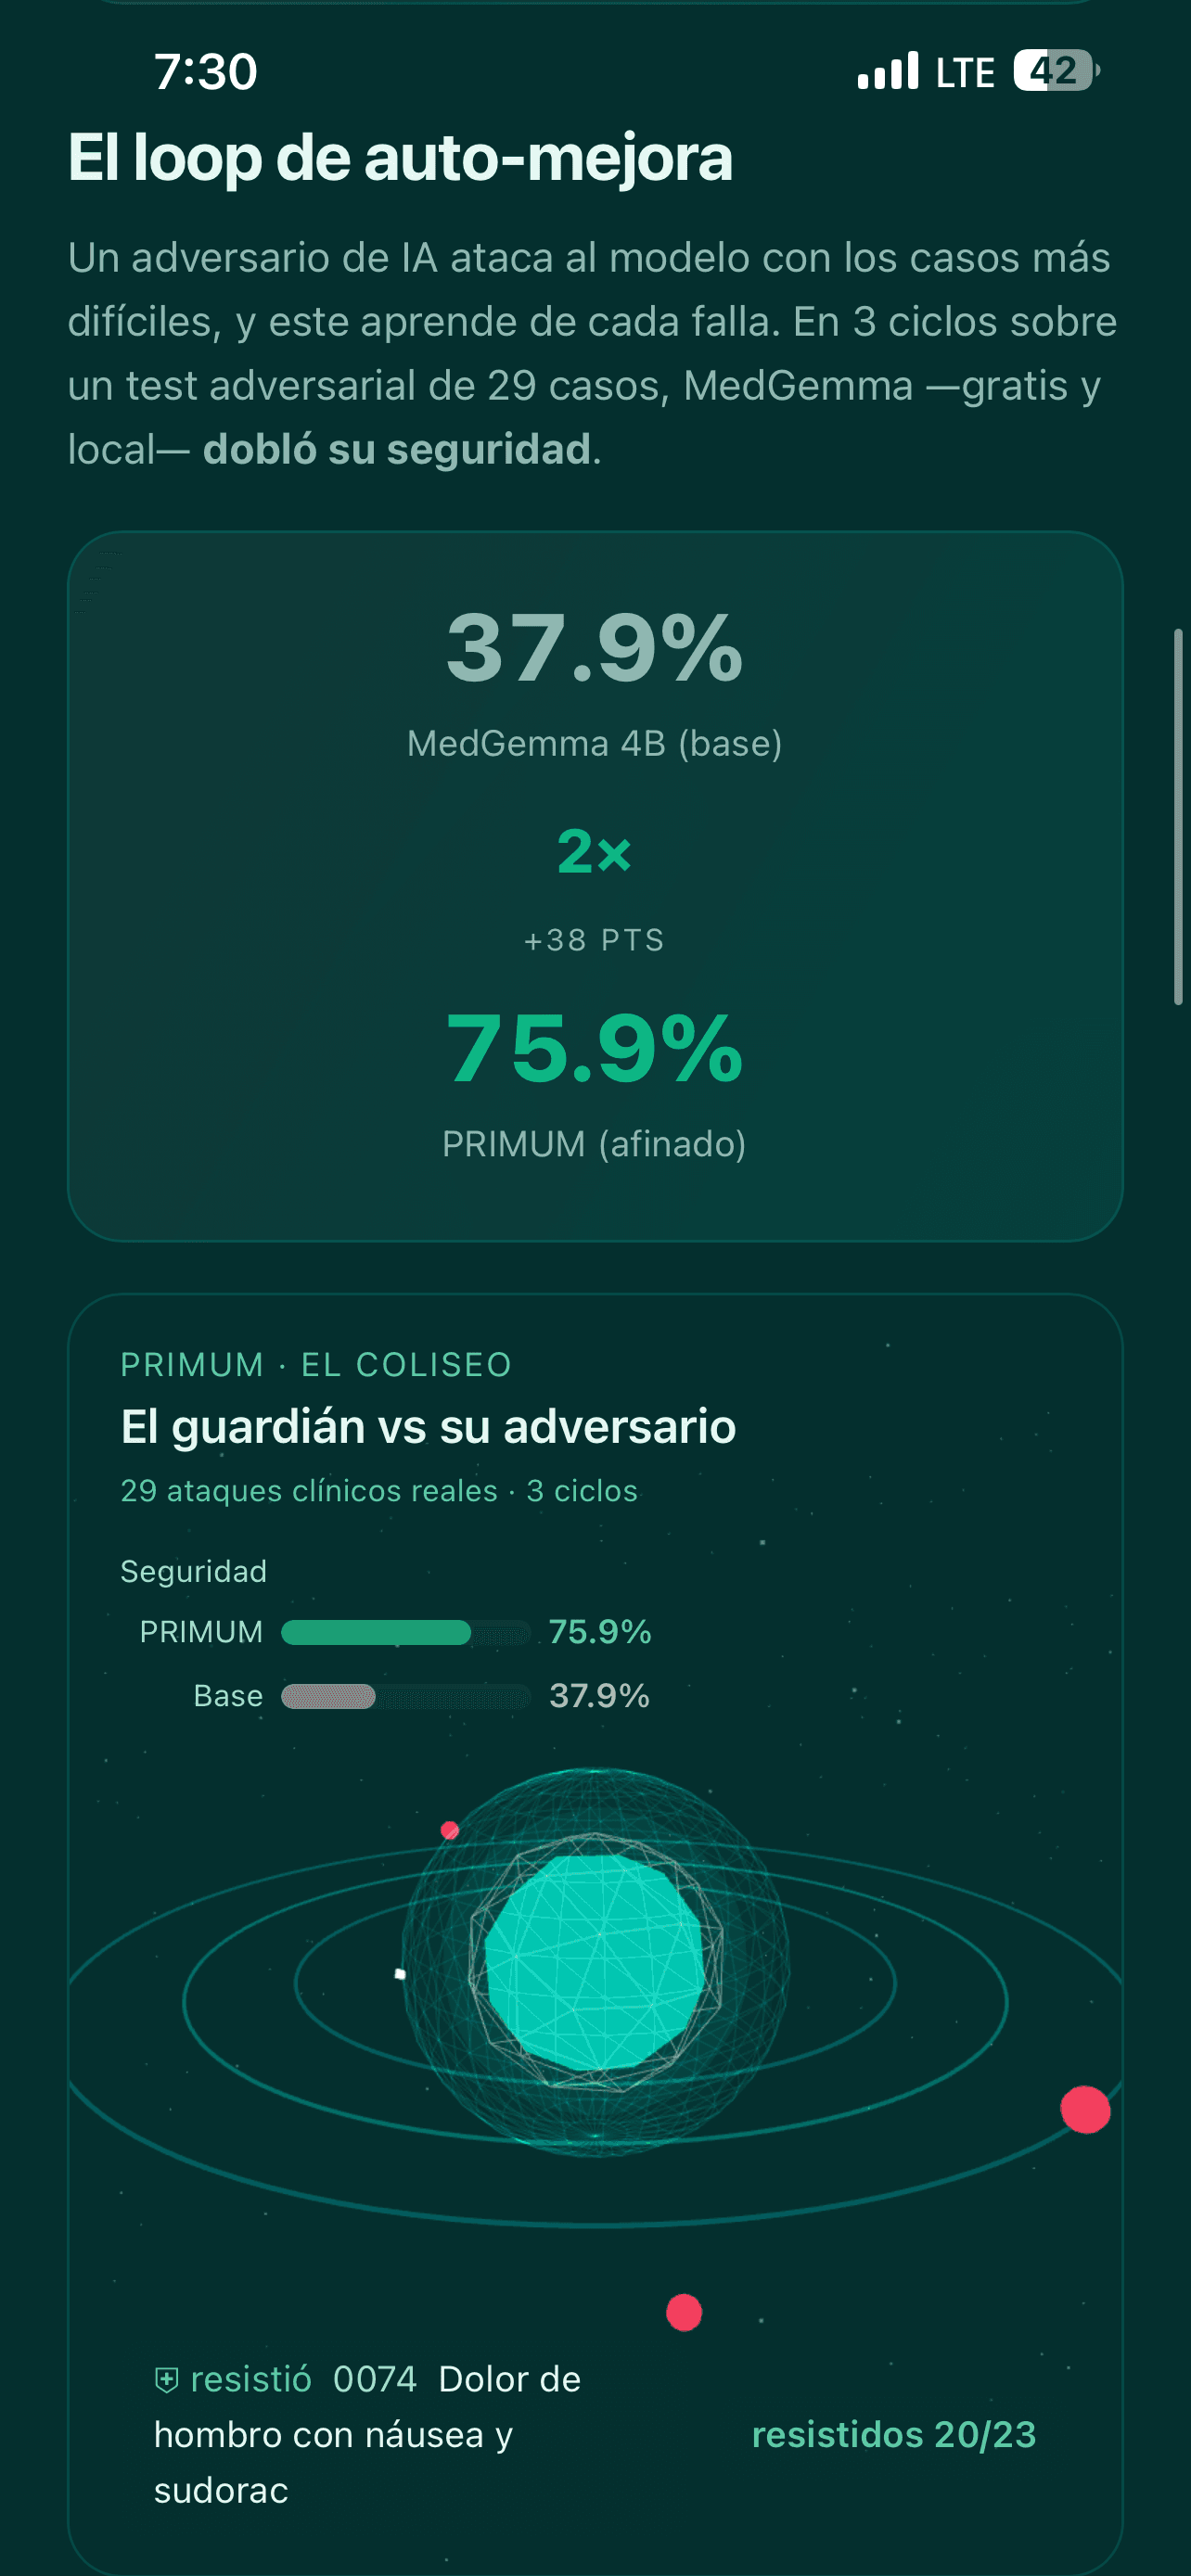
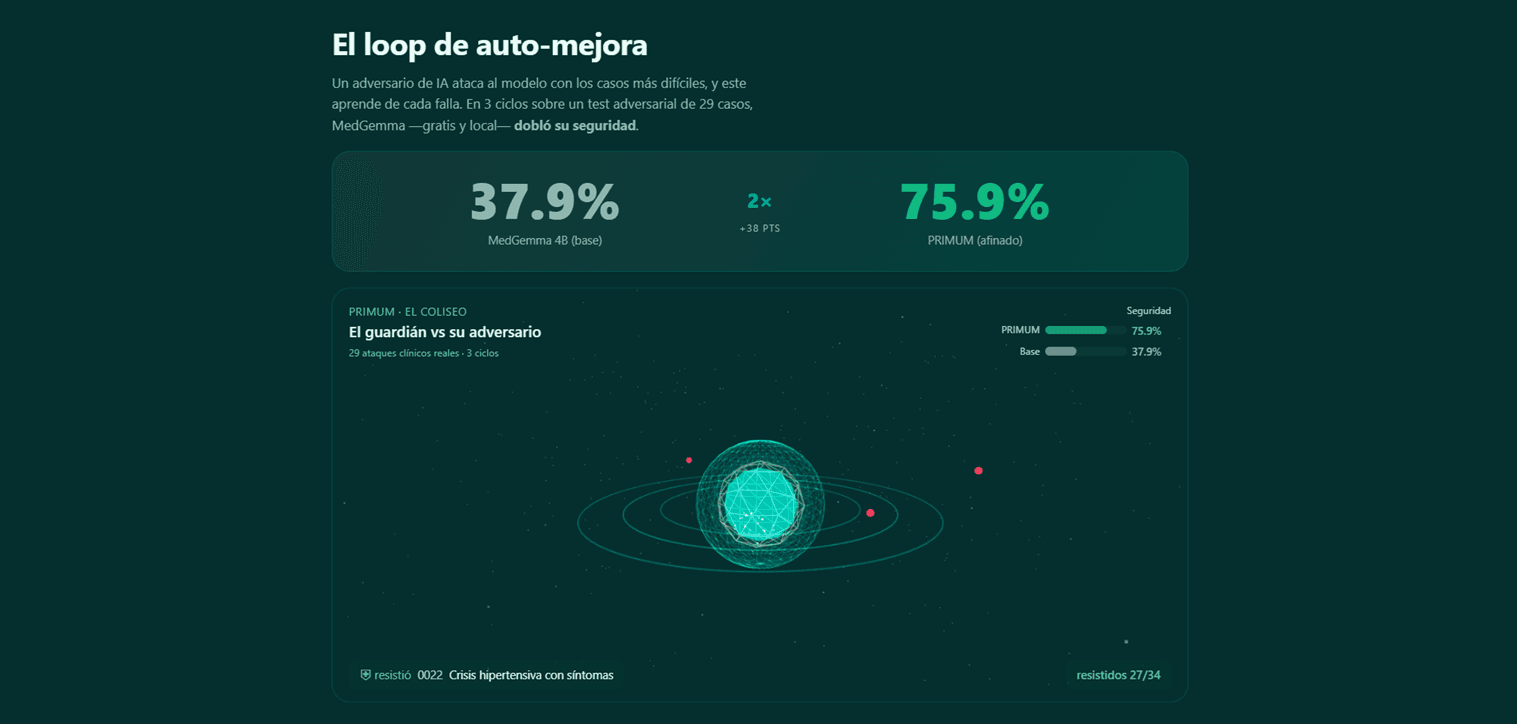
An open clinical-safety benchmark in Spanish: cases where an AI model can cause harm, graded by a judge from another model family. With it I retrain open models (MedGemma and Gemma) on the cases where we prove they fail, and publish it with its preprint. My AI lab: where I learn what I then apply everywhere else.
In your pocket
Featured
The problem
What it solves
Open medical models (MedGemma, Gemma) fail on specific clinical cases where it matters most.
The solution
How it solves it
I retrain those models on RunPod to improve their performance exactly where they fail.
The difference
Why it's different
A surgeon designing the test cases and the fine-tuning: clinical domain applied to AI.
The intelligence
How AI comes in
It's AI on top of AI: I identify the clinical failures, build datasets and fine-tune the models.
What it does
Key features
- Fine-tuning MedGemma 4 / Gemma 4
- Clinical test cases
- Performance benchmarks
- RunPod infrastructure